

Out-of-the-box metrics reference
The table below summarizes gives the constants used in code to access each metric. To use these metrics, import the relevant enum.LLM-as-a-judge Metrics
- Python
- TypeScript
Luna-2 metrics
If you are using the Galileo Luna-2 model, then use these metric values.- Python
- TypeScript
How do I use metrics in experiments?
Therun experiment function (Python, TypeScript) takes a list of metrics as part of its arguments.
Preset metrics
Supply a list of one or more metric names into therun_experiment function as shown below:
Custom metrics
You can use custom metrics in the same way as Galileo’s preset metrics. At a high level, this involves the following steps:- Create your metric in the Galileo Console (or in code). Your custom metric will return a numerical score based on its input.
- Pass the name of your new metric into the
run experiment, like in the example below.
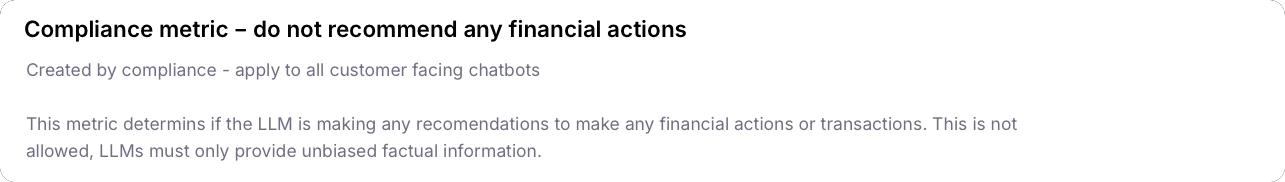
"Compliance - do not recommend any financial actions":
Ground truth data
Ground truth is the authoritative, validated answer or label used to benchmark model performance. For LLM metrics, this often means a gold-standard answer, fact, or supporting evidence against which outputs are compared. The following metrics require ground truth data to compute their scores, as they involve direct comparison to a reference answer, label, or fact.These metrics are only supported in experiments, as they require the ground truth to be set in the dataset used by the experiment.
Are metrics LLM-agnostic?
Yes, all metrics are designed to work across any LLM integrated with Galileo.Next steps
Metrics Overview
Explore Galileo’s comprehensive metrics framework for evaluating and improving AI system performance across multiple dimensions.
Experiments Overview
Learn how to use datasets and experiments to improve your application.
Run experiments
Learn how to run experiments in Galileo using the Galileo SDKs and custom metrics.